New models · weights you can run locally6
- 05:59
llama.cpp b11801
model: Add support for SenseNova U1 model ( #28919 ) model : add SenseNova U1 understanding support Add support for the dense SenseNova U1 understanding branch, including the U1.5-…
llama.cpp ReleasesRead - 15:54
KRAFTON/Raon-1-mini-preview · Hugging Face
Raon-1 mini is a 30B-A4B Mixture-of-Experts (MoE) language model, designed and trained from scratch by KRAFTON AI . It demonstrates strong capabilities in Korean conversation and a…
r/LocalLLaMARead
- 08:00
AnyLanguageModel 1.0: One Year of Local Models on Apple Platforms
Last November, we introduced AnyLanguageModel on this blog: a drop-in replacement for Apple's Foundation Models framework that lets you choose the model and provider your app uses.…
Hugging Face BlogRead - 08:00
Clef is available on Ollama's cloud
Clef, a 27B multimodal decision model from Cloudflare, is now available on Ollama. Users can run it locally or on Ollama’s cloud. Clef turns a state and a schema of typed questions…
Ollama BlogRead - 08:00
Reflection's Beam is freely available on Ollama for a limited time
Reflection’s first open-weight model Beam is generally available as of this morning, and we’re day-zero partners rolling it out on Ollama for free (for a limited time only!). In co…
Ollama BlogRead - 08:00
Run AI agents safely with Ollama and Fly.io
Ollama Cloud now works inside full Linux computers designed for agents using Fly.io Sprites. A Sprite is a sandbox from Fly.io. Each one is a full Linux virtual machine with its ow…
Ollama BlogRead

Hardware · NPUs / GPUs / edge devices5
- 02:11
Tried running 748B DeepSeek-V4.1-Flash on a €2k PC
I bought a used PC with an RTX 3090 24 GB, 128 GB DDR4 and an Intel i9-9900X last year for under €2,000. With the release of DeepSeek-V4.1-Flash-1017 I decided to try running it on…
r/LocalLLaMARead
- 23:38
Ran DeepSeek V4.1 Flash 1017 on a single RTX 5090
Been working over the last few days getting DeepSeek V4.1 Flash 1017 (Unsloth UD-IQ1_S) running in Basalt (inference engine I'm developing). Specs: RTX 5090 (400W) + RTX 5060 Ti 16…
r/LocalLLaMARead - 14:19
Be prepared, GPU price increase incoming --> Samsung sells out 100% of all 2027 HBM capacity - HBM prices expected to jump 200% next year, DRAM prices expected to see a double-digit price increase
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead
- 19:49
VAST开源实时世界模型EdenLive!单消费级显卡、720P超24FPS
据VAST介绍,EdenLive首次实现了在实时生成的前提下,同时完成任意参考输入、任意画风生成和长时连续运行。 具体来说,给它简化场景或参考视频,再配上目标首帧和提示词,就能沿着参考的布局与运动,持续生成写实、二次元等不同画风的精细画面。 参考来源可以不同,生成画风可以指定,而这些变化都能在实时生成过程中呈现。 在单张消费级显卡Nvidia RTX 509…
量子位Read - 21:48
端侧跑通超千亿大模型!联想YOGA Pro 15 RTX Spark超级AIPC今日正式发售
10月16日,联想YOGA Pro 15 RTX Spark超级AIPC全渠道正式开售,官方售价29999元起。作为全球首批搭载NVIDIA RTX Spark™ N1X超级芯片的本地智能体AIPC,这款产品宣告端侧AI正式跨越了对云端的过渡性依赖,全面赋能AI创作、编程开发与研学(学术科研与数据分析)人群,重塑个人生产力边界。 在联想YOGA家族的产品矩阵…
量子位Read
Faster inference · tokens-per-second tech12
- 06:34
llama.cpp b11803
models : add Flint model (FlintForCausalLM) ( #30928 ) Add Flint model (FlintForCausalLM). Assisted by Codex cleanup one more Co-authored-by: Sigbjørn Skjæret sigbjorn.skjaeret@hug…
llama.cpp ReleasesRead - 06:17
llama.cpp b11802
jinja : fix namespace attributes shadowed by dict methods ( #30941 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/58411998 macOS/iOS:…
llama.cpp ReleasesRead - 05:29
models: Add Flint model (FlintForCausalLM) by alexey-rsi · Pull Request #30928 · ggml-org/llama.cpp
now you can use Flint in llama.cpp (merged after 6h) Model specifications Property Flint Developer Recursive Architecture Decoder-only mixture-of-experts Transformer Total paramete…
r/LocalLLaMARead
- 05:18
llama.cpp b11800
llama: create new fused op for QSA mask ( #30640 ) llama: create new fused op for QSA scoring enroll glm5.3-next too tests : initialize the remaining tensors in test_kpool_mask The…
llama.cpp ReleasesRead - 03:00
Mica v0.5: The smartest 4B decision model is also the fastest one. 20 ms per answer, 25x faster than Jev
I'm sharing Mica v0.5, the follow-up to Mica v0.1. It's 4B and runs on one consumer GPU. On speed, it takes 19.8 ms per decision at 256 tokens and about 1.2 s at 32k on a single RT…
r/LocalLLaMARead
- 02:19
Amazing free 3090 speedup hack, verified works 15% PP, 5% TG for free
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead
- 01:55
llama.cpp b11799
sycl: q8 fast dequant ( #30775 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/58318564 macOS/iOS: macOS Apple Silicon (arm64) macOS A…
llama.cpp ReleasesRead - 00:40
llama.cpp b11798
jinja: support hexadecimal string escapes ( #30929 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/58290954 macOS/iOS: macOS Apple Sil…
llama.cpp ReleasesRead - 00:04
llama.cpp b11797
ggml-opencl : add IM2COL_3D support ( #30895 ) ggml-opencl : add IM2COL_3D support Assisted-by: OpenCode opencl: use same type for kernel and host opencl: fix for older adreno Co-a…
llama.cpp ReleasesRead - 20:39
llama.cpp b11796
mtmd: add state object for mtmd_gen ( #30902 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/58202944 macOS/iOS: macOS Apple Silicon (…
llama.cpp ReleasesRead - 20:20
llama.cpp b11795
server : forward llama.cpp sampling params on /v1/messages ( #30856 ) server : forward llama.cpp sampling params on /v1/messages server : pass the request through on /v1/messages i…
llama.cpp ReleasesRead - 19:58
llama.cpp b11793
llama : optimize vocabulary loading ( #30679 ) llama : optimize vocabulary loading Update src/unicode.h Co-authored-by: Georgi Gerganov ggerganov@gmail.com CR : added reserve in gg…
llama.cpp ReleasesRead
Community12
- 06:55
Recursive Flint - the "Qwen3.8 35B" we've all been waiting for?
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead
- 06:24
Inference time abliteration
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 05:36
minicpm5-2B-SFT-Abiliterated
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead
- 04:21
Qwen researching Qwen
I always feel a little bad asking LLMs to do research into itself or newer versions. It's like asking someone to face their own mortality, although that's anthropomorphizing. The u…
r/LocalLLaMARead - 03:57
If the bubble bursts we keep local AI forever
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead
- 03:34
llama: create new fused op for QSA mask by am17an · Pull Request #30640 · ggml-org/llama.cpp
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead
- 00:12
When will we see these changes? --> China Is Doubling RAM Production to Keep Everyday Gadget Prices from Skyrocketing
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead
- 00:00
Now that 3090 frenzy warning post makes sense.
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead
- 23:59
IBM Granite Speech 5.0 2B
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead
- 23:53
OK, fine, Qwen 3.8 Flash Next is nice
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 23:38
RecursiveSI/flint (40B A2.5B) · Hugging Face
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 23:27
inclusionAI/Ming-3.0-TTS-0.5B
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead
Local AI · latest47
- 06:55
Recursive Flint - the "Qwen3.8 35B" we've all been waiting for?
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 06:34
llama.cpp b11803
models : add Flint model (FlintForCausalLM) ( #30928 ) Add Flint model (FlintForCausalLM). Assisted by Codex cleanup one more Co-authored-by: Sigbjørn Skjæret sigbjorn.skjaeret@hug…
llama.cpp ReleasesRead - 06:24
Inference time abliteration
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 06:17
llama.cpp b11802
jinja : fix namespace attributes shadowed by dict methods ( #30941 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/58411998 macOS/iOS:…
llama.cpp ReleasesRead - 05:59
llama.cpp b11801
model: Add support for SenseNova U1 model ( #28919 ) model : add SenseNova U1 understanding support Add support for the dense SenseNova U1 understanding branch, including the U1.5-…
llama.cpp ReleasesRead - 05:36
minicpm5-2B-SFT-Abiliterated
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 05:29
models: Add Flint model (FlintForCausalLM) by alexey-rsi · Pull Request #30928 · ggml-org/llama.cpp
now you can use Flint in llama.cpp (merged after 6h) Model specifications Property Flint Developer Recursive Architecture Decoder-only mixture-of-experts Transformer Total paramete…
r/LocalLLaMARead - 05:18
llama.cpp b11800
llama: create new fused op for QSA mask ( #30640 ) llama: create new fused op for QSA scoring enroll glm5.3-next too tests : initialize the remaining tensors in test_kpool_mask The…
llama.cpp ReleasesRead - 04:21
Qwen researching Qwen
I always feel a little bad asking LLMs to do research into itself or newer versions. It's like asking someone to face their own mortality, although that's anthropomorphizing. The u…
r/LocalLLaMARead - 03:57
If the bubble bursts we keep local AI forever
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 03:34
llama: create new fused op for QSA mask by am17an · Pull Request #30640 · ggml-org/llama.cpp
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 03:00
Mica v0.5: The smartest 4B decision model is also the fastest one. 20 ms per answer, 25x faster than Jev
I'm sharing Mica v0.5, the follow-up to Mica v0.1. It's 4B and runs on one consumer GPU. On speed, it takes 19.8 ms per decision at 256 tokens and about 1.2 s at 32k on a single RT…
r/LocalLLaMARead - 02:19
Amazing free 3090 speedup hack, verified works 15% PP, 5% TG for free
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 02:11
Tried running 748B DeepSeek-V4.1-Flash on a €2k PC
I bought a used PC with an RTX 3090 24 GB, 128 GB DDR4 and an Intel i9-9900X last year for under €2,000. With the release of DeepSeek-V4.1-Flash-1017 I decided to try running it on…
r/LocalLLaMARead - 01:55
llama.cpp b11799
sycl: q8 fast dequant ( #30775 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/58318564 macOS/iOS: macOS Apple Silicon (arm64) macOS A…
llama.cpp ReleasesRead - 00:40
llama.cpp b11798
jinja: support hexadecimal string escapes ( #30929 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/58290954 macOS/iOS: macOS Apple Sil…
llama.cpp ReleasesRead - 00:12
When will we see these changes? --> China Is Doubling RAM Production to Keep Everyday Gadget Prices from Skyrocketing
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 00:04
llama.cpp b11797
ggml-opencl : add IM2COL_3D support ( #30895 ) ggml-opencl : add IM2COL_3D support Assisted-by: OpenCode opencl: use same type for kernel and host opencl: fix for older adreno Co-a…
llama.cpp ReleasesRead - 00:00
Now that 3090 frenzy warning post makes sense.
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 23:59
IBM Granite Speech 5.0 2B
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 23:53
OK, fine, Qwen 3.8 Flash Next is nice
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 23:38
Ran DeepSeek V4.1 Flash 1017 on a single RTX 5090
Been working over the last few days getting DeepSeek V4.1 Flash 1017 (Unsloth UD-IQ1_S) running in Basalt (inference engine I'm developing). Specs: RTX 5090 (400W) + RTX 5060 Ti 16…
r/LocalLLaMARead - 23:38
RecursiveSI/flint (40B A2.5B) · Hugging Face
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 23:27
inclusionAI/Ming-3.0-TTS-0.5B
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 21:12
35B MoE running at 20.5 tok/s on an iPhone, without skipping experts
I came across OpenBMB’s engineering write-up on running large MoE models locally, and the systems work behind it is worth highlighting. Instead of shrinking the model or skipping e…
r/LocalLLaMARead
- 20:59
I built a small on-device voice front-end for local assistants: type any wake word, keep only your voice before STT (5 models, 7.5 MB, Apache-2.0, early preview)
GitHub: https://github.com/alkove-ai/alkove (Apache-2.0, code and weights) Hi r/LocalLLaMA , A bit about me first: my day job is building LLM systems in production, a tool-calling…
r/LocalLLaMARead
- 20:39
llama.cpp b11796
mtmd: add state object for mtmd_gen ( #30902 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/58202944 macOS/iOS: macOS Apple Silicon (…
llama.cpp ReleasesRead - 20:20
llama.cpp b11795
server : forward llama.cpp sampling params on /v1/messages ( #30856 ) server : forward llama.cpp sampling params on /v1/messages server : pass the request through on /v1/messages i…
llama.cpp ReleasesRead - 20:00
[Paper] MemT-1.0: Towards Memory-Native Evolution
Memory-native evolution requires making memory an intrinsic capability of foundation models, enabling them to continuously accumulate and utilize information. To this end, we intro…
r/LocalLLaMARead
- 19:58
llama.cpp b11793
llama : optimize vocabulary loading ( #30679 ) llama : optimize vocabulary loading Update src/unicode.h Co-authored-by: Georgi Gerganov ggerganov@gmail.com CR : added reserve in gg…
llama.cpp ReleasesRead - 18:09
[Paper] Specter: Fast MoE Inference via Quantization-Enabled Multi-Step Speculative Offloading
Mixture-of-experts (MoE) models often exceed a single accelerator's memory capacity. Offloading experts to host memory creates a severe PCIe I/O bottleneck because data-dependent r…
r/LocalLLaMARead
- 17:41
Qwen3.8-Flash-Next vs Opus 5.5: Six-way benchmark on a real Rust feature with Claude Code and Pi
Reposting again since original post got removed by Reddit for some reason (I have no idea why) A few of you pointed out in my last post that comparing Flash-Next and Opus with diff…
r/LocalLLaMARead - 15:54
KRAFTON/Raon-1-mini-preview · Hugging Face
Raon-1 mini is a 30B-A4B Mixture-of-Experts (MoE) language model, designed and trained from scratch by KRAFTON AI . It demonstrates strong capabilities in Korean conversation and a…
r/LocalLLaMARead - 14:19
Be prepared, GPU price increase incoming --> Samsung sells out 100% of all 2027 HBM capacity - HBM prices expected to jump 200% next year, DRAM prices expected to see a double-digit price increase
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 09:24
EXCLUSIVE: ByteDance, Alibaba, Tencent place over $35 billion worth of Nvidia chip orders
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 08:00
AnyLanguageModel 1.0: One Year of Local Models on Apple Platforms
Last November, we introduced AnyLanguageModel on this blog: a drop-in replacement for Apple's Foundation Models framework that lets you choose the model and provider your app uses.…
Hugging Face BlogRead - 22:30
[Bi-Weekly Megathread] Project Showcase
We’re committed to safety and security. But not for bots. Complete the challenge below and let us know you’re a real person.
r/LocalLLaMARead - 18:10
客户为什么愿意为端侧 AI 买单?五位一线操盘手讲透了
过去几年,AI 行业热衷于比参数、拼算力、讲融资。但模型一旦离开展台,客户的问题立刻具体起来:数据会不会泄露?设备能不能 24 小时运行?响应够不够快?噪声大不大? 这些问题,正把端侧 AI 推到产业舞台中央。 10 月 14 日,后摩智能在北京开了一场生态合作伙伴大会。期间,极客公园创始人 & CEO 张鹏主持了一场圆桌,五位来自不同赛道的人坐到了一起:麒…
极客公园Read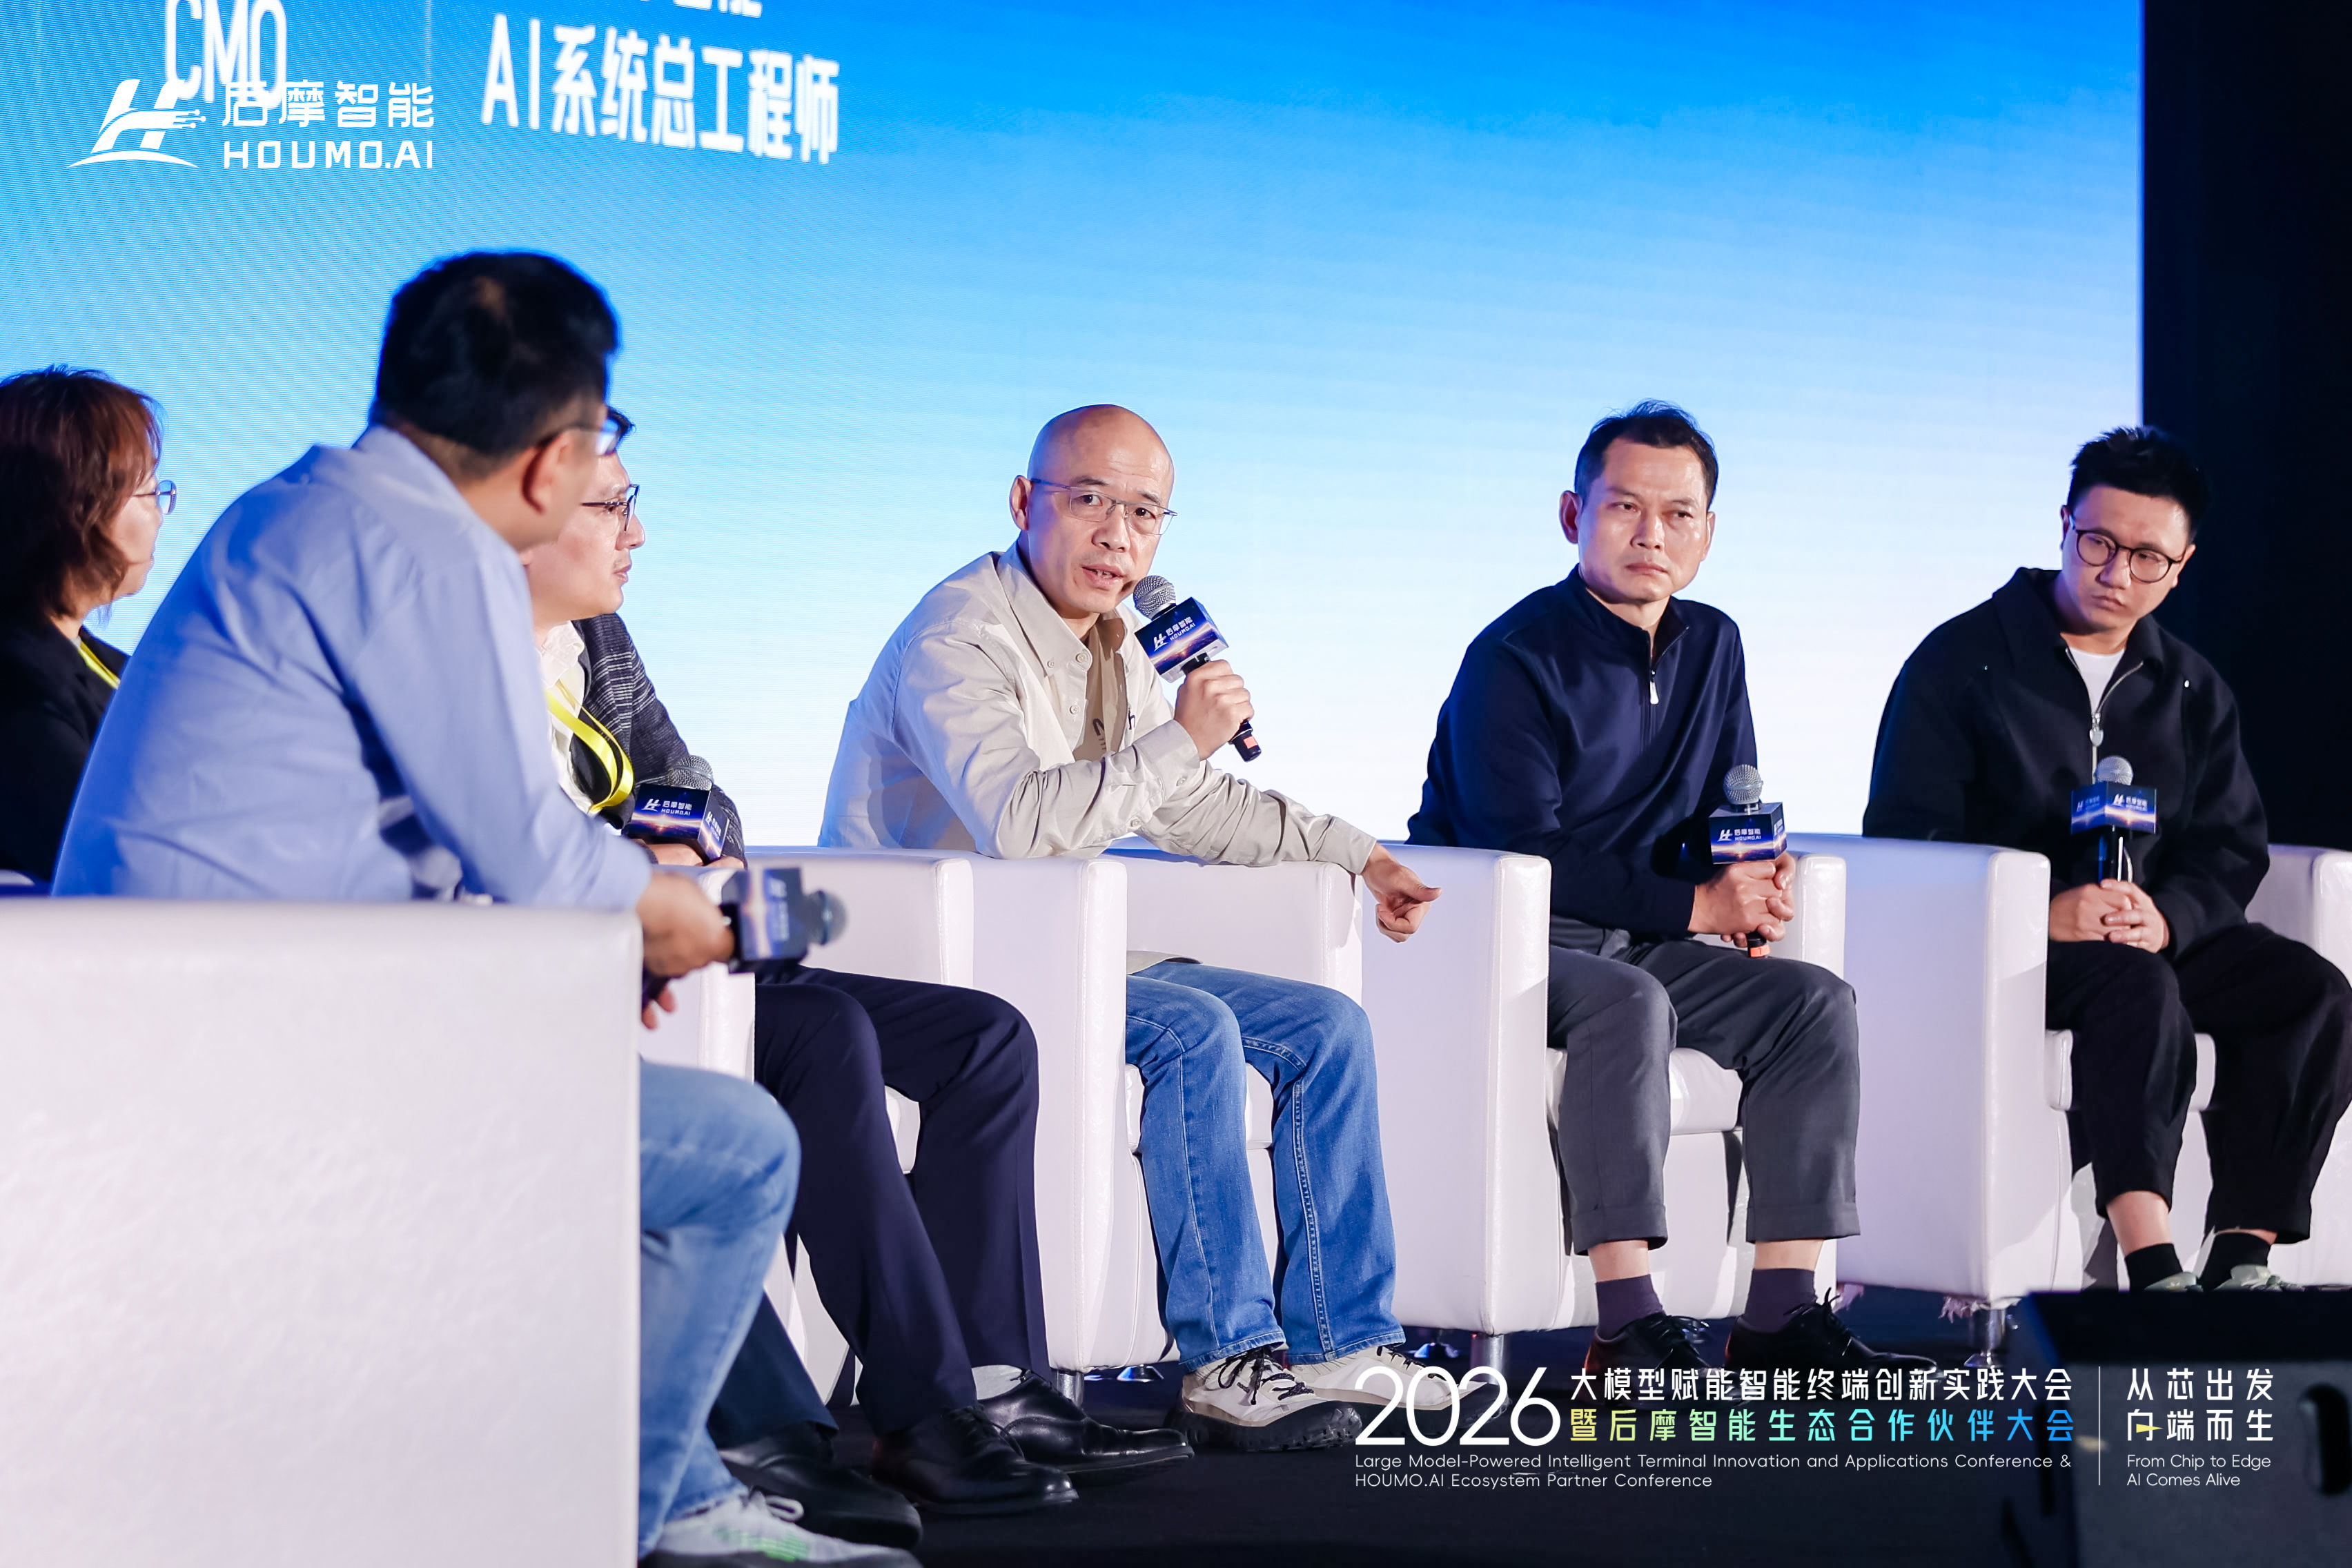
- 08:00
Clef is available on Ollama's cloud
Clef, a 27B multimodal decision model from Cloudflare, is now available on Ollama. Users can run it locally or on Ollama’s cloud. Clef turns a state and a schema of typed questions…
Ollama BlogRead - 19:49
VAST开源实时世界模型EdenLive!单消费级显卡、720P超24FPS
据VAST介绍,EdenLive首次实现了在实时生成的前提下,同时完成任意参考输入、任意画风生成和长时连续运行。 具体来说,给它简化场景或参考视频,再配上目标首帧和提示词,就能沿着参考的布局与运动,持续生成写实、二次元等不同画风的精细画面。 参考来源可以不同,生成画风可以指定,而这些变化都能在实时生成过程中呈现。 在单张消费级显卡Nvidia RTX 509…
量子位Read - 02:26
Open source and on device: the strategy behind Nvidia’s new AI models
The new Nemotron 3.5 models show how the AI giant is focusing on reinforcing its own GPU infrastructure while supporting the open source community. Amid the accelerating race betwe…
AI BusinessRead
- 21:48
端侧跑通超千亿大模型!联想YOGA Pro 15 RTX Spark超级AIPC今日正式发售
10月16日,联想YOGA Pro 15 RTX Spark超级AIPC全渠道正式开售,官方售价29999元起。作为全球首批搭载NVIDIA RTX Spark™ N1X超级芯片的本地智能体AIPC,这款产品宣告端侧AI正式跨越了对云端的过渡性依赖,全面赋能AI创作、编程开发与研学(学术科研与数据分析)人群,重塑个人生产力边界。 在联想YOGA家族的产品矩阵…
量子位Read - 08:00
Reflection's Beam is freely available on Ollama for a limited time
Reflection’s first open-weight model Beam is generally available as of this morning, and we’re day-zero partners rolling it out on Ollama for free (for a limited time only!). In co…
Ollama BlogRead - 03:55
Amazon devices chief Panos Panay sees a future where AI devices replace the need to use apps
TechCrunch AIRead - 07:37
Apple MLX v0.32.4
What's Changed Adding VJP for the scaled dot product attention. by @tpegolotti in #4563 python: Add pos support to array by @aaishwarymishra in #4488 Add Python 3.15 and 3.15t supp…
Apple MLX ReleasesRead - 01:05
Run fast, private agents on-device with LFM2.5-24B-A2B
LFM2.5-24B-A2B is a 24B-parameter reasoning model with just 2B active parameters, built for fast, private agents on-device. It thinks before it answers, calls tools, and works thro…
Hugging Face BlogRead - 08:00
Run AI agents safely with Ollama and Fly.io
Ollama Cloud now works inside full Linux computers designed for agents using Fly.io Sprites. A Sprite is a sandbox from Fly.io. Each one is a full Linux virtual machine with its ow…
Ollama BlogRead
